Anatomy of a Memory Leak: How to Analyze .NET Core Dump Files in Linux Production
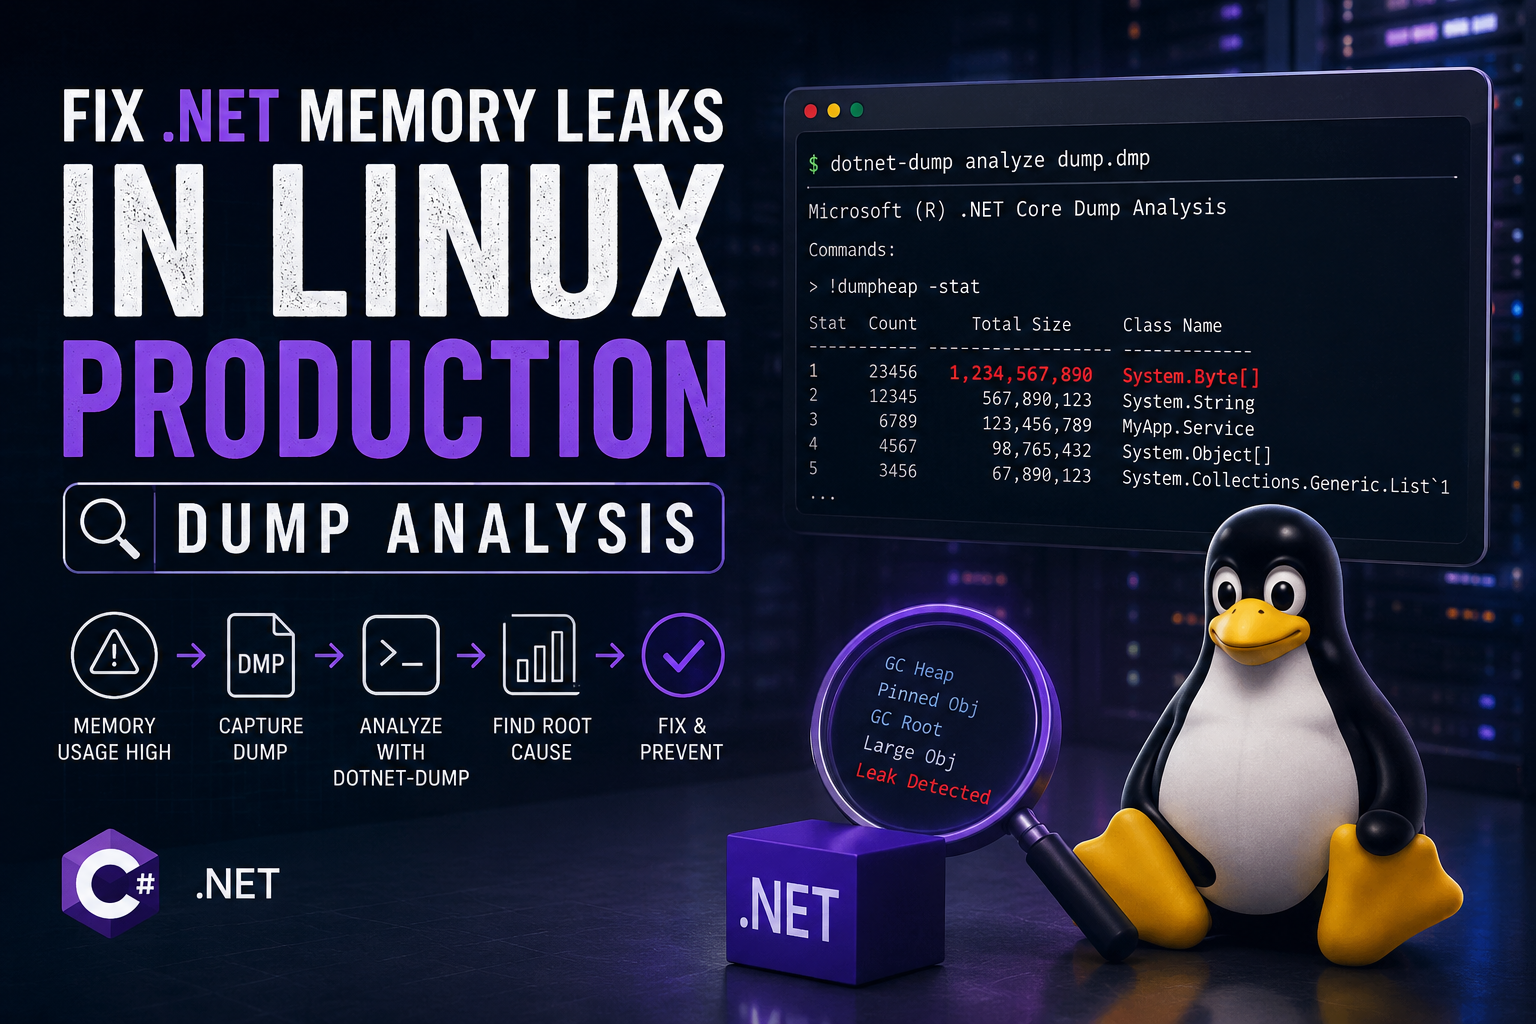
It’s 3:00 AM on a Thursday. Your phone is buzzing violently on the nightstand. You blink against the harsh glare of your screen to see a PagerDuty alert that makes your stomach drop: Pod restart on Kubernetes cluster. Reason: OOMKilled. Just last week, your senior dev assured you that provisioning those containers with 4GB of RAM was overkill for a standard .NET Core web API. Yet, looking at the Grafana dashboard, there it is—the classic, agonizingly perfect 45-degree upward slope in memory consumption over the last three days.
Congratulations, you have a memory leak. And if your team is like most I’ve led over the past 15 years, the immediate instinct will be to log into the cloud console, bump the memory limit to 8GB, hit restart, and go back to sleep.
Don’t do that. Bumping RAM or writing a cron job to cycle your pods every midnight isn’t engineering; it’s firefighting with cardboard boxes. It kicks the can down the road while hiding systemic architectural flaws. When your application is running locally in Windows with Visual Studio comfortably attached, tracking down memory bloat is easy. But when it’s stripped down, containerized, running on a secure Linux distro in a production VPC, standard debugging tricks fall completely flat.
Let’s walk through the exact, zero-fluff playbook I teach my senior engineers for capturing and analyzing .NET Core dump files directly from live Linux production environments.
The Hidden Trap: Why Linux Memory Leaks Feel Different
Before running a single command, we need to clear up a massive misconception that routinely trips up brilliant engineers transitioning from standard Windows environments to Linux containers.
In the Linux eco-system, the kernel manages memory aggressively. I constantly see developers look at the RES (Resident Set Size) memory via top or a Prometheus metric, see it sitting at 85%, and frantically ping the team slack channel.
But here’s the reality: High memory utilization does not equal a memory leak. In .NET, the Garbage Collector (GC) is highly sophisticated. If your API is running in Server GC mode—which is the default for ASP.NET Core—the GC splits the managed heap into multiple segments per CPU core. It doesn’t eagerly yield memory back to the Linux host because operating system allocation calls are incredibly expensive. It assumes that if it needed that memory slice five minutes ago, it will probably need it again soon.
A true, structural memory leak only occurs when objects are allocated to handle business logic, finish their job, but cannot be reclaimed because a surviving root object still holds a hard reference to them.
Step 1: Capturing the Evidence (Without Hitting the Self-Destruct Button)
To fix a leak, you need a snapshot of the managed heap at the height of the bloat. This is your core dump file.
Years ago, pulling a core dump on Linux meant installing massive, intrusive packages like gdb or configuring the host OS to drop massive system core dumps on crash. Good luck getting your security or platform engineering team to approve that on a hardened, minimal production container image.
Thankfully, the modern .NET diagnostics suite gives us a lightweight, production-grade tool called dotnet-dump.
Installing the Tool on a Live Container
If you have a container that is actively bleeding memory right now, you can exec directly into it to download and run the tool on the fly.
# Exec into your running production container
kubectl exec -it <pod-name> -n production -- /bin/bash

# Download the standalone dotnet-dump tool
curl -L -o dotnet-dump https://aka.ms/dotnet-dump/linux-x64
chmod +x ./dotnet-dump
An EM’s Note on Reality: In strict corporate environments, your production pods won’t have public internet access to fetch tools via
curl. Don’t wait for an outage to figure this out. Work with your platform team to bakedotnet-dumpdirectly into your base enterprise Docker images, or set up a diagnostics sidecar pattern.
Triggering the Dump
First, identify the Process ID (PID) of your running application. Since .NET typically serves as the container’s entry point, it’s almost always PID 1. You can double-check this by running ./dotnet-dump ps.
Once you have the PID, pull the trigger:
./dotnet-dump collect -p 1 --type Full -o /tmp/app_leak.dmp
CRITICAL WARNING: A Full dump writes the entire physical memory footprint of your process directly to disk. If your app is currently choking on 3.5GB of RAM, your dump file is going to be 3.5GB. If your container storage or /tmp volume doesn’t have that much headroom, you will instantly fill the disk and crash the container yourself. Always verify disk space before running this command.
Step 2: The Post-Mortem Analysis
Once you’ve securely pulled that .dmp file out of the environment and onto a local machine or an isolated diagnostics environment, it’s time to perform the analysis.
Launch the interactive CLI tool:
dotnet-dump analyze /path/to/app_leak.dmp
If you’ve ever had to use WinDbg on legacy Windows servers, this command interface will feel like home. Here are the exact commands you need to execute, step-by-step.
1. The Overview: dumpheap -stat
This is always your first move. It prints every single object type currently sitting on your managed heap, aggregated by total memory consumption.
> dumpheap -stat

MT         Count    TotalSize Class Name
00007f9a12b4 Free        14,201    45,120,400      Free
00007f9a15a2       420    24,510,120 System.Byte[]
00007f9b0124   150,432    32,110,800 System.String
00007f9a88c1   125,000   120,500,000 MyCompany.Orders.Services.OrderContext
How to evaluate this: Scroll straight to the bottom. Ignore the Free rows—that’s just unallocated padding space inside the heap segments. Look for your specific business domain objects or common system types (System.String, System.Byte[]) showing an astronomical count.
In the example above, MyCompany.Orders.Services.OrderContext has 125,000 distinct instances alive on the heap simultaneously. For a stateless HTTP API, that is a glaring structural red flag.
2. Isolate the Targets: dumpheap -mt <MethodTable>
Now that we know OrderContext is hoarding our memory, grab its Method Table (MT) address from the leftmost column (00007f9a88c1) and pull up the specific instances:
> dumpheap -mt 00007f9a88c1

         Address               MT     Size
00007f93a0112010 00007f9a88c1       964
00007f93a0115c28 00007f9a88c1       964
00007f93a0119840 00007f9a88c1       964
3. Find the Jailer: gcroot <ObjectAddress>
This is where the mystery is solved. Why hasn’t the GC vaporized these instances? What object is keeping them alive?
Grab a single instance address from the previous output and pass it to gcroot:
> gcroot 00007f93a0112010
The terminal will trace the reference path backwards, showing you exactly what object chain anchors your leaking instance to an immutable GC Root (like a long-running thread or static variable):
Thread 7f9b1200 (Action Thread):
    -> 00007f93a0051010 MyCompany.Orders.Services.OrderCache
    -> 00007f93a0051050 System.Collections.Generic.List`1[[MyCompany.Orders.Services.OrderContext]]
    -> 00007f93a0112010 MyCompany.Orders.Services.OrderContext
The Discovery: Look closely at that reference chain. An OrderCache service configured as a Singleton is holding a generic List inside it, and references to every OrderContext used during a web request are being systematically appended to it. The cache grows infinitely, the references stay unbroken, and the GC is technically blocked from doing its job.
3 Common Architectural Anti-Patterns I See Teams Build
Throughout my career reviewing production microservices, memory leaks rarely stem from runtime bugs. Instead, they almost always trace back to one of three classic architectural design flaws.
1. The Captive Dependency
This occurs when a long-lived service (like a Singleton) implicitly captures a short-lived service (like a Transient or Scoped component).
If an engineer injects a Scoped DbContext directly into the constructor of a Singleton background worker, that specific DbContext instance is trapped for the entire lifecycle of the application. Every query executed tracks entities locally, bloating the context instance forever.
2. The Unsubscribed Event Handler (The Silent Culprit)
When Object A subscribes to an event exposed by Object B, Object B keeps an internal reference to Object A within its delegate invocation list.
public class PriceNotifier {
    public event EventHandler PriceChanged;
}

// Inside a scoped HTTP request handler:
_priceNotifier.PriceChanged += OnPriceChanged;
If PriceNotifier is an application-wide singleton event broker, and your scoped request handler forgets to explicitly clean up after itself using the unsubscribe operator (-=), that handler will remain anchored on the heap for the remainder of the process’s life.
3. Misconfigured Client Factories
Manually spinning up a new HttpClient inside a traditional using block for every single outbound network request is a known anti-pattern. While the managed client gets disposed, the underlying network sockets remain stuck in a kernel TIME_WAIT state, leading to socket exhaustion under heavy load.
However, overcompensating by holding a static reference to an HttpClient forever means your application will completely ignore external upstream DNS updates. The standard resolution is leveraging IHttpClientFactory, but implementing it carelessly without proper handler lifetime configurations can lead to a massive backlog of un-disposed internal message handlers.
The Operational Playbook for Tech Leaders
Fixing a memory leak reactively is great engineering; building a system where they can’t make it to production is strong leadership. Here is the operational protocol I enforce across my development teams:
-
Validate Dependency Injection Lifetimes Early: Don’t wait for runtime crashes. Force your application to validate dependency lifetimes explicitly inside
Program.csduring staging and local development phases. It will instantly throw an exception on startup if a singleton attempts to capture a scoped dependency.C#var builder = WebApplication.CreateBuilder(args); // Hard-stop improper DI registrations before they hit production builder.Host.UseDefaultServiceProvider((context, options) => { options.ValidateScopes = true; options.ValidateOnBuild = true; }); -
Enforce Soak Testing: Never push large-scale data processing engines or major architectural changes out based on a standard unit test pass. Run automated soak tests (using k6 or Locust) against your staging cluster for at least two consecutive hours under consistent load, and scrutinize the memory trend line. If it doesn’t plateau, the pull request does not get approved.
-
Velocity-Based Alerting: Switch your APM alerting logic away from static thresholds (e.g., alert when memory usage hits 90%) and focus on velocity tracking (e.g., alert if memory usage increases steadily over a continuous 12-hour window). This gives your engineers days to diagnose a problem rather than minutes in the middle of the night.
Summary: Real Engineers Don’t Guess
When a core production system begins to degrade, the pressure from product management and executive stakeholders to simply restart the service and move on can be intense.
But true technical leadership is about choosing root-cause analysis over quick fixes. Taking the extra 20 minutes to pull a structured dump file, navigate the heap, and isolate the exact gcroot eliminates future recurring outages, protects system integrity, and keeps cloud infrastructure bills from ballooning.
The next time one of your container pods drops dead from an out-of-memory error, don’t just clear the alert. Treat it as a direct look into how your codebase behaves under real stress. Grab dotnet-dump, look at the raw data, and let the facts guide your fix.